Modulate Raises $25M to Scale Its Lead in Frontier Audio-Native AI
Future Ventures-led round brings Modulate's funding to $60 million as the company expands its frontier AI models,

Press Release Disclaimer: This is a press release distributed through the XPR Media network. It has not been independently verified by our newsroom.


Future Ventures-led round brings Modulate’s funding to $60 million as the company expands its frontier AI models, developer ecosystem and partner network
BOSTON, MA / ACCESS Newswire / September 28, 2026 / Modulate, the frontier audio AI company, today announced $25 million in new funding led by Future Ventures, with participation from Hyperplane and Lakestar, to accelerate growth as demand rapidly increases for AI that can understand the full context of human voice. The new capital will support continued development of Modulate’s pioneering audio-native AI models and the expansion of its developer and partner ecosystems. The investment comes as Modulate advances its technology and market reach, with growing adoption of its audio AI models across fraud prevention, voice AI agent supervision, customer experience, trust and safety, and other emerging voice applications.
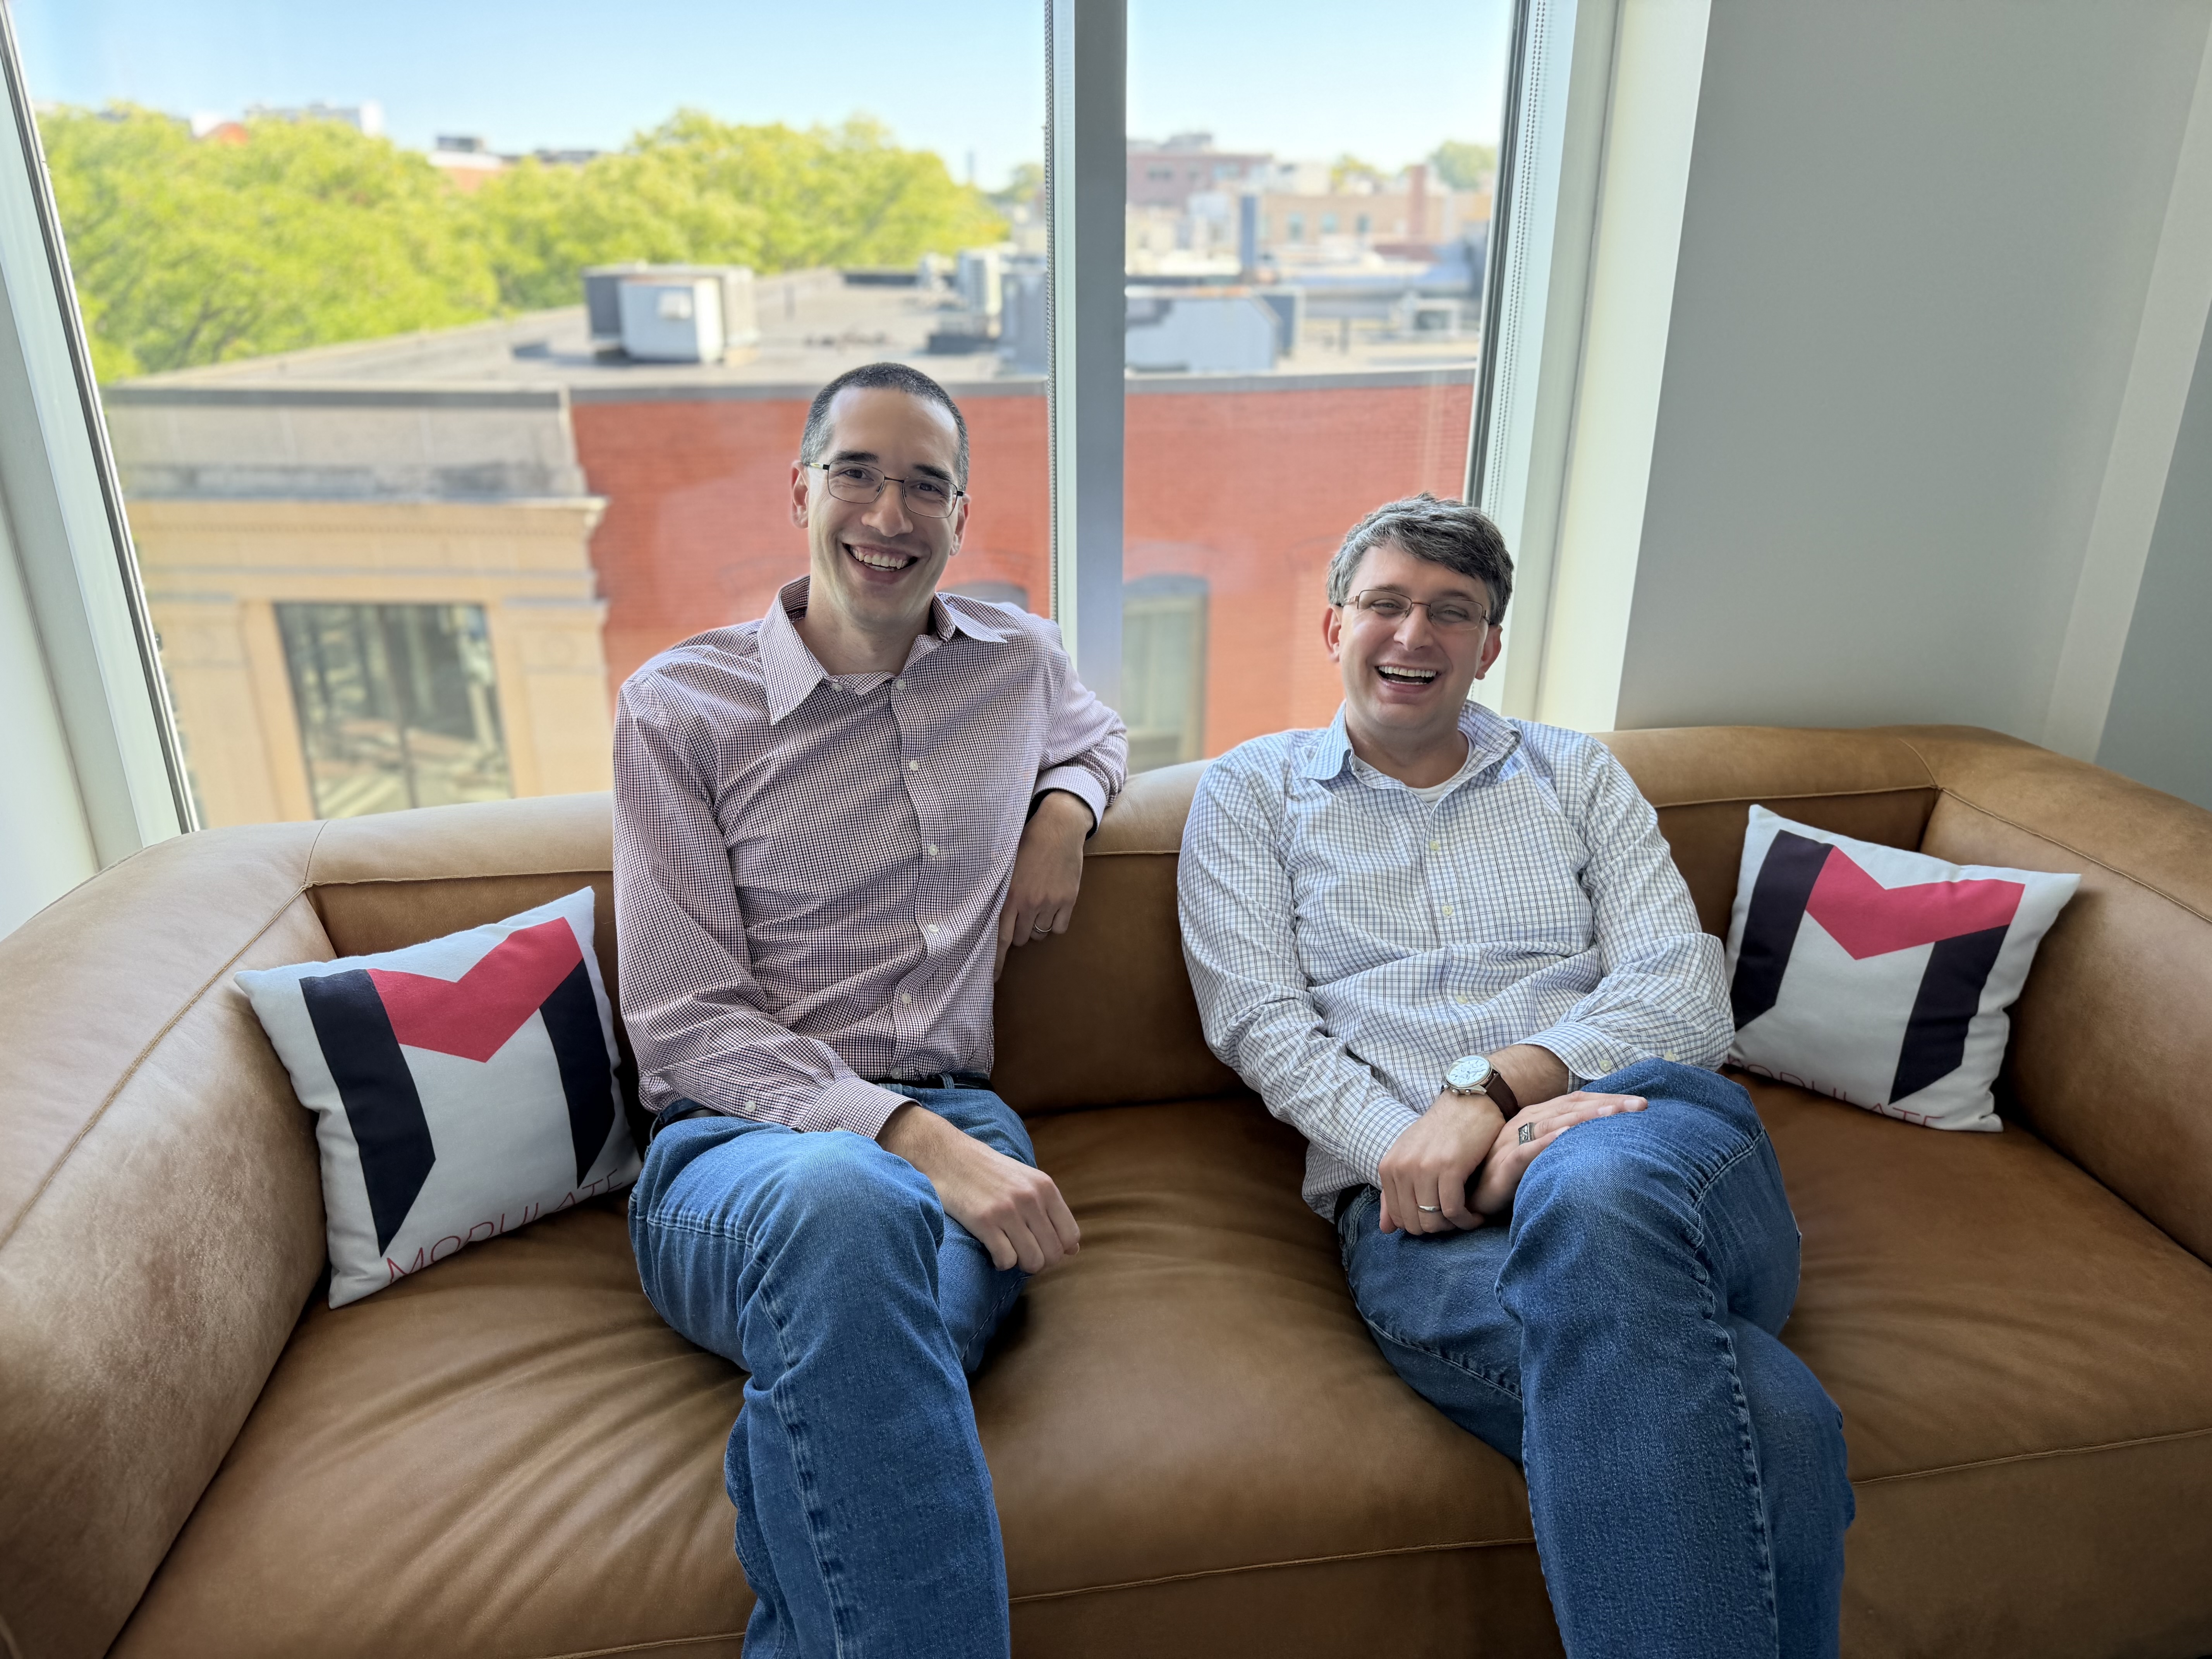
With this funding, Modulate plans to increase investment across AI/ML research, product and engineering, developer relations, and partnerships, while continuing to broaden the APIs, models, and deployment options available to developers.
The investment follows a period of significant technical and commercial momentum for Modulate. Its models now analyze more than 10 million hours of audio each month, recently surpassing over 600 million hours of audio processed in total, while its transcription and deepfake detection technologies both ranked #1 on public benchmarks like Hugging Face, the industry’s authoritative platform for leaderboards, evaluation datasets, and standardized model testing.
Modulate’s audio-native models are used every day to protect healthcare institutions from deepfake hackers; enhance voice AI agent’s emotion and empathy capabilities; reduce extremism and harassment on social platforms; observe and monitor voice agent performance; detect and stop child grooming voice conversations; and protect agents in high-risk scenarios from being identified through advanced voice masking – among a growing number of use cases. Modulate is now expanding the team and infrastructure needed to meet growing demand from developers and partners building voice applications across security, customer experience, communications, AI agent supervision, and trust and safety.
“Voice is becoming a primary interface for AI, and that creates a whole new set of problems that can’t be solved from a transcript,” said Carter Huffman, CEO and co-founder of Modulate. “We’re already using audio-native AI to protect organizations from deepfake attacks, help voice agents understand emotion and respond with more empathy, identify dangerous behavior in online conversations, and monitor whether voice agents are actually performing the way they’re supposed to. Underneath all of that are more than a hundred specialized models working together to understand what’s really happening across audio, with dramatically less cost and compute than traditional large models.”
Building the understanding layer for voice AI
As investment pours into AI systems that can speak naturally, Modulate is focused on the other side of the interaction: helping machines accurately understand what is happening in a voice conversation.
Modulate’s flagship Velma platform is the leading model for understanding conversations, with 2x greater accuracy than traditional LLMs at detecting true positive results and 7x fewer false positive results. Velma analyzes audio directly to identify signals including emotion, tone, intent, emphasis, synthetic speech, and conversational behaviors. Those signals can be used independently or composed to recognize higher-level events, from fraud attempts and AI agent failures to harassment, customer dissatisfaction, and policy violations. Velma can operate in real time, enabling applications not only to understand what happened in a conversation, but to intervene while it is still happening.
The underlying technology powering Velma is Modulate’s Ensemble Listening Model architecture, or ELM. Rather than relying on a single massive foundation model, Modulate’s ELM orchestrates more than 100 specialized audio models, selecting and combining them to deliver highly accurate results while substantially reducing the compute required for inference. Velma has demonstrated up to 1,000x greater efficiency than a single large model approach, reducing the cost, energy and memory required to analyze audio at scale.
With more than 600 million hours of audio analyzed, that technical approach is already producing measurable results. Modulate recently earned the number-one position on Hugging Face’s Open ASR Leaderboard for transcription and currently ranks first on Hugging Face’s deepfake speech benchmark. Its transcription API is priced at $0.03 per hour for batch processing, while its deepfake detection technology achieves 98.9% accuracy on public benchmark data.
Voice AI enters the real world
Modulate’s voice-native technology is already solving an expanding set of real-world problems. Its models can help organizations detect synthetic voices and suspicious behavior in high-risk calls; identify when a voice AI agent is frustrating or misunderstanding a customer; detect harassment, grooming and other harmful behavior on social and gaming platforms; and give developers audio-native signals that allow AI applications to respond more appropriately to the people using them.
Steve Jurvetson, Co-founder of Future Ventures and Board member of SpaceXAI, said, “Modulate has gained a significant technical lead in audio-native AI, and the market opportunity is expanding quickly. The team has proven these models in some of the most demanding voice environments in the world, and we’re now seeing the need for that technology to expand well beyond where it started into AI agents, security, customer experience, and more. This investment will help Modulate move faster, grow the team, put its models into the hands of more developers and partners, and establish audio intelligence as a foundational layer of the AI stack.”
The funding will also support Modulate’s growing developer and partner strategy. The company is building new industry models, expanding its developer tooling with new SDKs and APIs, increasing developer relations resources, creating partner integrations, and supporting new deployment environments for customers. With these additional resources, Modulate is giving companies building voice agents, communications platforms, security products, and other audio applications a way to incorporate sophisticated audio understanding without developing specialized models themselves.
“Developers shouldn’t have to rebuild the audio intelligence layer every time they create a new voice experience,” Huffman added. “Our mission is to build the models and infrastructure that let them focus on the application they want to create. The opportunity facing audio-native AI is expanding incredibly quickly. We’ve built the technology and proven it at scale, and this investment lets us grow the team and move faster to meet that demand.”
With the new capital, Modulate is scaling the team, technology and developer ecosystem behind its broader ambition: making audio-native intelligence a foundational layer wherever voice AI is built.
Download the Modulate press kit here.
About Modulate
Modulate is a frontier audio AI company building audio-native models that power the next generation of voice AI, enabling machines to understand the nuances in human conversation beyond the words being spoken. Its Velma platform is powered by Modulate’s Ensemble Listening Model (ELM) architecture, bringing together more than 100 specialized models to understand signals including emotion, tone, intent, synthetic speech and conversational behavior and create a powerful layer of audio intelligence for voice applications. Founded by MIT alumni, Modulate’s technology has analyzed more than 600 million hours of audio and is used across AI agents, fraud and deepfake detection, customer experience, trust and safety, and other emerging voice applications.
For more information or to get started, visit modulate.ai.
Media Contact
Kristin Canders
Grithaus Agency
207-974-7744
(e) kristin@grithaus.agency
###
SOURCE: Modulate
View the original press release on ACCESS Newswire
Media gallery